Overview
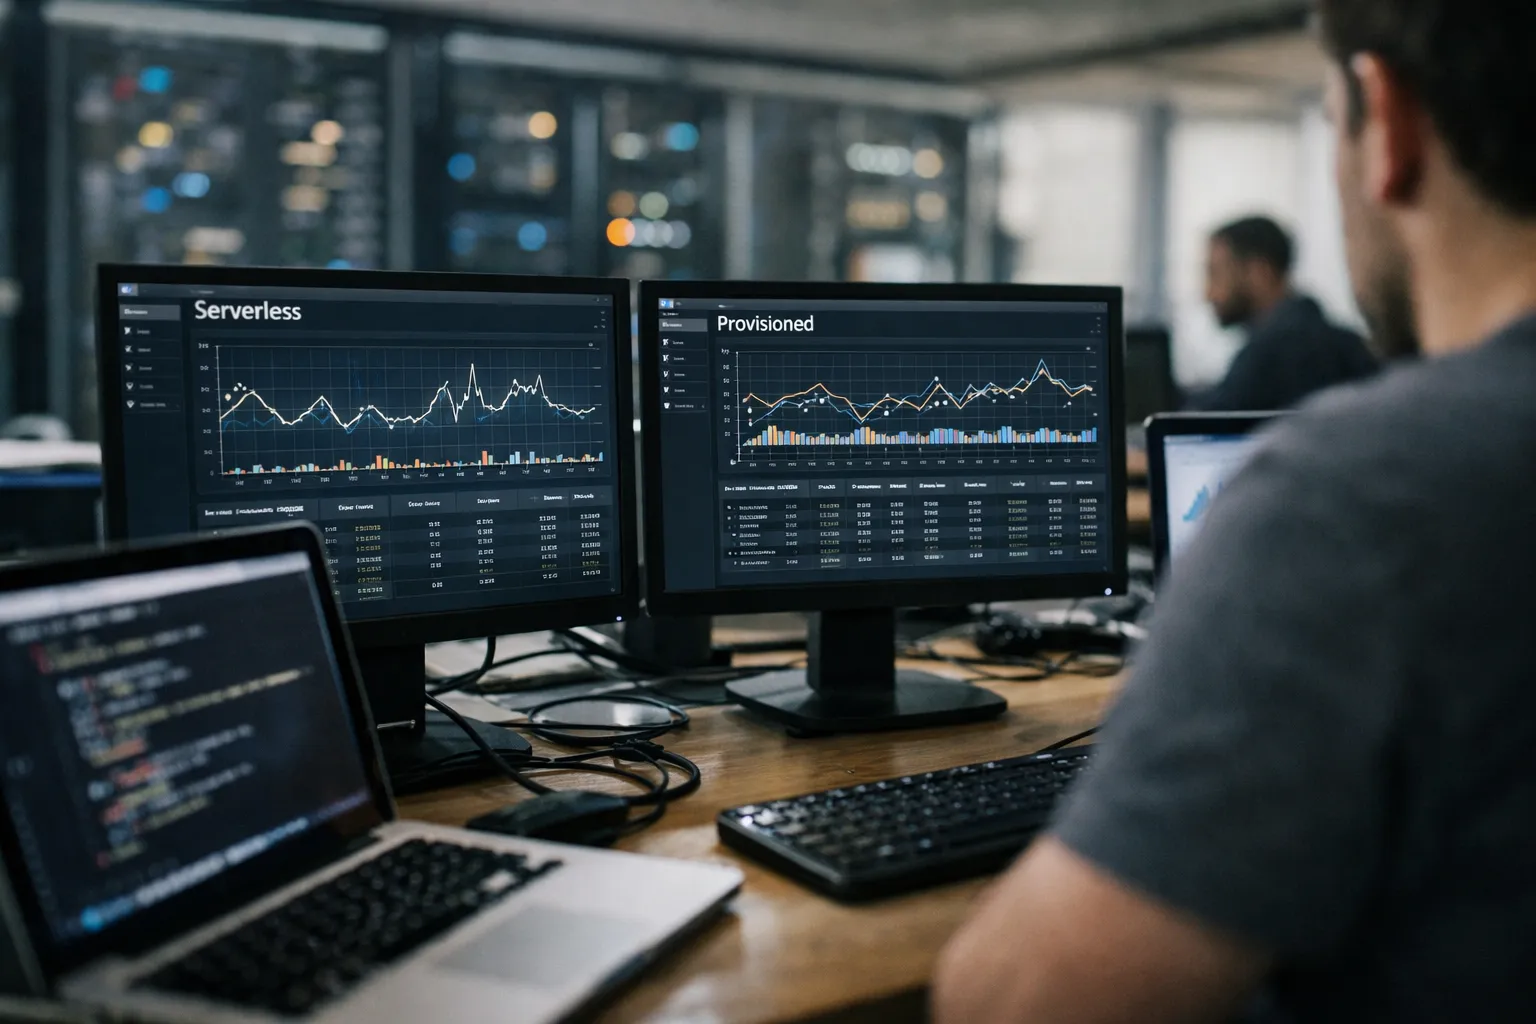
Data teams increasingly face the same question in 2026: should interactive, high‑concurrency analytics run on serverless SQL engines (BigQuery, Redshift Serverless, Snowflake Serverless SQL, Databricks Serverless SQL) or on provisioned warehouses/compute clusters (Snowflake virtual warehouses, Redshift RA3-style clusters, provisioned Databricks clusters)? The answer affects query latency and queueing, cloud costs, operational burden, and the ability to meet SLOs for internal or customer‑facing dashboards.
This update brings the discussion current to October 2026: vendors have narrowed some early gaps (faster warm pools, tighter SLAs), third‑party routing and FinOps tooling matured, and operational best practices have crystallized. Below I summarize evidence, practical tradeoffs, and an updated decision checklist you can use this quarter.
Background
Between 2023 and 2026 two forces reshaped the choice. First, serverless SQL matured quickly: vendors invested in warm‑pool infrastructure, premium low‑latency tiers, and richer telemetry APIs. Second, analytics adoption kept rising—embedded analytics, self‑service BI, and growth in real‑time dashboards produced more concurrent users and unpredictable spikes.
The net effect: serverless looks less like an experimental convenience and more like a realistic option for many production analytics workloads. Still, the tradeoffs remain: serverless simplifies capacity ops but changes how you govern cost and latency; provisioned clusters restore control and predictability at the price of capacity management.
Data & Evidence (what to watch in your telemetry)
Here are the core, verifiable dimensions to measure in your environment and how they have shifted through 2026:
- Pricing model and predictability. Serverless engines still bill on consumption (bytes scanned, per‑second DBU/credits). Vendors now commonly offer commitment discounts and burstable reservation models—meaning you can buy a baseline commit and still burst serverless. That hybrid billing reduces surprises but requires careful usage tagging to attribute costs.
- Concurrency and queuing. Provisioned clusters continue to provide deterministic concurrency proportional to reserved resources. Serverless has improved autoscaling and added priority queues in some offerings; however, hard limits and soft queuing still appear during extreme, noisy spikes. The practical lesson: measure queue time and queue depth in production—these are your single best indicators of when provisioned capacity is needed.
- Cold starts and latency. Typical cold starts for serverless have fallen in many offerings from "tens of seconds" to single‑digit seconds on premium tiers or when warm pools are enabled. Cold starts are not eliminated; they have become less frequent and shorter, but still noticeable for sub‑second SLOs.
- Data locality and caching. Provisioned clusters still win when you rely on warm local caches, pinned SSDs, or tuned I/O paths for repeated hot queries. Serverless providers improved internal caching and result caches—useful for dashboards that hit identical queries—but cache eviction policies and cross‑tenant effects require verification.
- Observability and governance. A major 2026 development: vendors exposed finer per‑query telemetry (plan stages, queueing, bytes per stage) and third‑party FinOps tools added automated policy enforcement for ephemeral compute. Still, telemetry gaps remain unless you enforce strict query labeling and use the provider APIs to ingest metrics into your observability stack.
Concrete measurement you should collect now: per‑query wall time, parse/plan/execute breakdown, queue time, bytes scanned, DBU/credits, query tags (dashboard|user|product), and cache hit rates. Don’t guess—measure for 2–4 weeks covering a peak reporting window.
Multiple Perspectives
Different teams continue to view the tradeoffs through distinct lenses:
- Platform engineers tend toward provisioned clusters when they must guarantee latency, isolate noisy tenants, or preserve warm caches. Many platform teams now combine reserved baseline clusters with serverless burst to reduce wasted capacity while protecting SLAs.
- FinOps and finance leaders appreciate serverless’s pay‑for‑use model but insist on tagging and automated budgets. In 2026, several organizations adopted "baseline+burst" purchase patterns to retain predictability while keeping burst flexibility.
- Analytics product managers and customers want consistent, low latency. Their preference is for provisioned capacity for mission‑critical dashboards, with serverless layered for ad‑hoc and exploratory work.
- Vendors now sell tiered execution: standard serverless, premium low‑latency paths, and managed routing/priority options. These aim to close the user‑experience gap, but they often carry extra cost and operational complexity.
Implications for Data Teams
Choosing the wrong model still leads to the same three risks, but how you mitigate them has evolved:
- User experience erosion. Queueing, even if brief, breaks analyst flow. Use SLOs (p95 latency, p99 queue time) and error budgets to detect when serverless degradation becomes business‑visible.
- Cost surprises. Serverless is less opaque than it was in 2024, but burstable workloads can still cause overruns. Enforce quotas, alerting, and per‑query chargeback in your billing pipeline.
- Operational blind spots. Improved telemetry helps—if you actually ingest and act on it. If you don’t tag queries, you won’t be able to apply targeted fixes.
Practical tip: don’t skip per‑query labeling. In my experience helping teams migrate, the single fastest lever to control cost is a label that ties queries back to a dashboard or product feature. If you can’t measure which dashboard scans terabytes, you can’t optimize or assign ownership.
Updated Decision Framework: When to Use Which (Oct 2026)
Use this checklist as a pragmatic decision tree—measure first, then act.
- Choose serverless when:
- Your workload is bursty and unpredictable and you lack the ops bandwidth to manage capacity.
- You accept occasional short cold starts or can route critical queries elsewhere.
- You have per‑query telemetry, cost quotas, and automated budget controls in place.
- Choose provisioned clusters when:
- You need strict, repeatable p95/p99 latency for internal or external SLAs.
- Hot, repeated queries benefit from warm caches or pinned resources.
- Your finance team prefers committed spend and you can operate autoscaling responsibly.
- Choose hybrid (recommended for most mature teams):
- Reserve baseline provisioned capacity sized to cover steady‑state concurrent dashboards.
- Use serverless for unpredictable ad‑hoc exploration, batch spikes, and non‑critical workloads.
- Implement routing rules (session tags, user groups) and a managed query router where available to automatically place queries based on SLA and cost policy.
Practical engineering actions (do these first)
- Implement per‑query labeling (dashboard_id, team, product) and export tags to your billing/observability system. Don’t skip this step—labels are the basis of accountability.
- Define SLOs for query latency and queue time; set error budgets and automated escalation for when budgets are exhausted.
- Run a 2–4 week A/B routing test across peak and off‑peak windows. Capture cost, latency breakdowns, queue time, and cache hit rates.
- Use precomputation (materialized views, aggregates) and result caching for hot dashboard queries. Over‑reliance on on‑the‑fly compute is expensive even on serverless.
- If using serverless, configure warming schedules where allowed and monitor cold starts; if warming is not supported, consider lightweight warmers via scheduled synthetic queries.
Outlook — What to Watch in Q4 2026 and 2027
- Managed routing and tiering will become mainstream. Expect more vendor or third‑party offerings that automatically route queries to baseline provisioned capacity or serverless based on policy—reducing manual governance overhead.
- FinOps for ephemeral compute will deepen. Expect more automated throttles, budget‑based routing, and per‑query cost remediation flows (block, warn, reroute) integrated into pipelines.
- Edge and locality features for serverless. Vendors may offer regional warm pools and locality controls that make serverless behave more like provisioned clusters for latency‑sensitive workloads.
If you plan a migration or capacity redesign this quarter, prioritize observability and governance work first. Those investments pay dividends regardless of whether you pick serverless, provisioned, or a hybrid approach.
FAQ
How should I test whether serverless actually reduces my costs?
Run a 2–4 week A/B experiment. Route a representative sample of dashboard and ad‑hoc queries to serverless and to provisioned clusters with identical datasets, labels and query timeouts. Capture per‑query cost (DBU/credits, bytes scanned), wall time, queue time, and cache hit rate. Include peak reporting windows. Normalize results by query class and report cost per business transaction (e.g., cost per dashboard refresh).
Can I eliminate cold starts entirely on serverless?
No—cold starts have been reduced but not eliminated in 2026. You can reduce impact with premium low‑latency tiers, vendor warm pools, scheduled light churn (warmers), and aggressive result caching. For sub‑second SLOs, provisioned capacity remains the safer option.
What observability signals are the highest priority?
Prioritize per‑query: total wall time, queue time, parse/plan/execute breakdown, bytes scanned, DBU/credits consumed, cache hit/miss, and tags tying a query to a dashboard or team. Correlate these with business identifiers to enable chargeback and targeted optimizations.
Is a hybrid model much harder to operate?
Hybrid adds complexity but is often the most pragmatic path. Automate routing, enforce labels, and use CI/CD for query changes. The operational cost is typically lower than the cost of poor UX or unexpected bills.
Closing note
Think of the choice like catering a large event: in 2026 serverless has better ovens and more flexible staff, but you still need a headcount plan and a budget cap. Provisioned clusters are your reserved dining room—predictable but requiring care to avoid empty seats. For most organizations, the right answer is both: reserve a predictable baseline, give analysts a serverless sandbox for exploration, and instrument everything so you can see who’s using what and why. Get the observability and governance in place first—you’ll sleep better, and your dashboards will keep serving the people who depend on them.